Outlier Analysis in Data Mining

What are Outliers?

Outliers are an integral part of data analysis. An outlier can be defined as observation point that lies in a distance from other observations.

An outlier is important as it specifies an error in the experiment. Outliers are extensively used in various areas such as detecting frauds, introducing potential new trends in the market and others.

Usually, outliers are confused with noise. However, outliers are different from noise data in the following sense:

  1. Noise is a random error, but outlier is an observation point that is situated away from different observations.
  2. Noise should be removed for better outlier detection.
Outlier Analysis in Data Mining

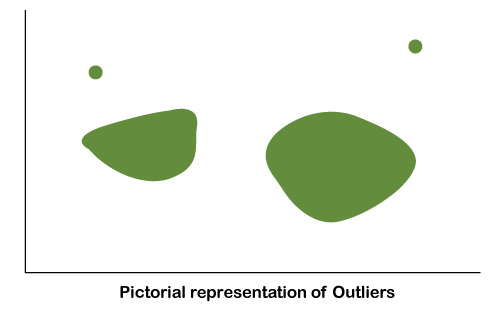
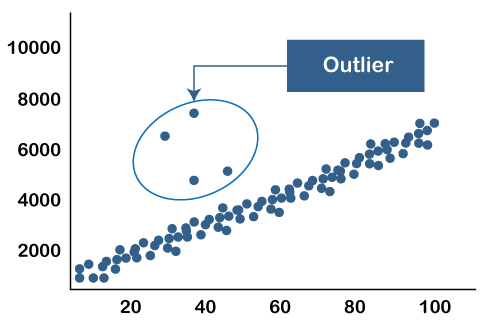
Given below are two graphical examples of outliers:

As shown in this graph, the outliers are points that lie outside the entire pattern of distribution.
Outlier Analysis in Data Mining

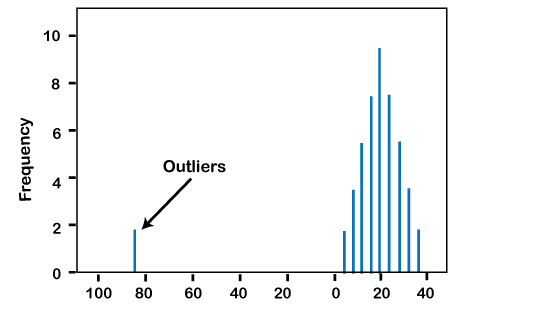
Another illustration of outliers can be seen in the histogram given below. In this, one point lies far away from the remaining, this point is an outlier.
Outlier Analysis in Data Mining

Various causes of outliers in Data Mining

There are various causes of outliers in Data Mining. Some of these causes are given below:

  1. It is used in identifying the frauds in banking sectors such as credit card hacking or any similar frauds.
  2. It is used in observing the change in trends of buying patterns of a customer.
  3. It is used in identifying the typing errors and reporting errors made by humans.
  4. It is used in discovering the errors or faults in machines or systems.

What is the need of handling the outliers in Data Mining?

There are various reasons to handle the outliers in Data Mining. Some of those reasons are listed below:

  1. Outliers affect the results of the databases.
  2. Outliers often give useful or beneficial results and conclusions due to which various trends or patterns can be recorded.
  3. Outliers can be beneficial in research department also. They can be extremely useful in some discovery.
  4. Outliers are the key branches of data mining.

Applications of Outlier Detection in Data Mining

In Data Mining, Outlier Detection is extensively used. It is used to obtain patterns or trends in data mining. The applications of Outlier Detection in Data Mining are given below:

  1. Fraud Detection
  2. Telecom Fraud Detection
  3. Intrusion Detection in Cyber Security
  4. Medical Analysis
  5. Environment Monitoring such as Cyclone, Tsunami, Floods, Drought and so on
  6. Noticing unforeseen entries in Databases

What is Outlier Analysis?

Outlier Analysis can be defined as the process in which abnormal or non-typical observations in a data set is identified.

Outlier Analysis can also be called “Outlier Mining”.

The outliers in Outlier Detection have a particular concern. These concerns are usually shown in fraud detection and intrusion detection. In fraud detection, the outliers show the fraudulent activity. Therefore, outlier detection and analysis are very beneficial part of data mining tasks. This process is known as “Outlier Mining” or “Outlier Analysis”.
Outlier Analysis in Data Mining

Different approaches in Outlier Detection

There are majorly three approaches observed in outlier detection. Those approaches are given below:

  1. The Statistical Approach
  2. The Distance Based Approach
  3. The Deviation Based Approach

Outlier Detection techniques

There are four major outlier detection techniques:

  1. Numeric
  2. Z-Score
  3. DBSCAN
  4. Isolation forest

Numeric:

This is the simplest method in a single dimensional feature space. In this method, the outliers are calculated with the help of IQR (InterQuartile Range) approach. It is also nonparametric.

Z-Score:

Z-score is a parametric outlier detection method in a single or low dimensional feature space. In Z-score technique, it is assumed that there is a Gaussian distribution of the data. Zi is calculated using the formula given below:

Zi = (xi - µ)/ ?

DBSCAN:

This Outlier Detection technique is based on the DBSCAN clustering method. DBSCAN is a nonparametric, density-based outlier detection method in one or more than one dimensional feature space. In this, all the data points are described as Core Points, Border Points or Noise Points.

Isolation Forest:

Isolation Forest is a nonparametric approach that is mainly designed for huge sets of data in a one or more than one dimensional feature space. In this approach, an essential concept is isolation numbers which can be defined as the number of splits required to isolate a data point.


Related Topics

Difference between Data Warehouse and Data Mining

Difference between Data Warehouse and Data Mining Data Warehouse: Data Warehousing is a technique that is mainly used to collect and manage data from various different sources so as to give the...

8 minutes read.

Data Mining Process

Data Mining Process Data mining is a process that can be defined as a process of extracting or collecting the data that is usable from a large set of data. Data Mining...

4 minutes read.

Data Mining Functionalities

Data Mining Functionalities The Data Mining functionalities are basically used for specifying the different kind of patterns or trends that are usually seen in data mining tasks. Data mining is extensively...

4 minutes read.

Data Mining Applications

Data Mining Applications: As we already know, Data Mining is very useful and beneficial as we can dig deeper into the data so as to explore more about it and...

4 minutes read.

Data Mining Steps

What is Data Mining? Data Mining can be defined as the process that enables a user to find or discover various patterns and trends in a vast and large amount of...

3 minutes read.

Data Mining Tasks

Data Mining Tasks Data Mining can be defined as the process of extracting important or relevant information from a set of raw data. In data mining, tasks can be categorized into two...

4 minutes read.

Data Mining Architecture

Data Mining Architecture: Data Mining can be defined as a process of extracting the data which is usable from huge sets of data. It is also known as KDD (Knowledge...

4 minutes read.

Association Rule in Data Mining

Association Rule in Data Mining What is meant by Association Rule? One may understand Association Rule as if-then statements. It is generally used for finding and obtaining frequent patterns, correlation, and association...

4 minutes read.

Data Cleaning in Data Mining

What is data cleaning? Data mining is concerned with extracting valuable information from the data, which can help organizations make business decisions. But before performing data mining, we have to clean the...

6 minutes read.

Cluster Analysis in Data Mining

Cluster Analysis in Data Mining What is meant by cluster analysis? Cluster analysis in data mining refers to the process of searching the group of objects that are similar to one and...

5 minutes read.

Major Issues in Data Mining

Major Issues in Data Mining: Data Mining is not very simple to understand and implement. As it is already evident that Data Mining is a process which is very crucial...

3 minutes read.

KDD in Data Mining

What is Data Mining and why is it needed? Data Mining can be defined as the process of extraction of useful and relevant information from a set of raw data. Data Mining...

4 minutes read.

Data Mining Algorithms

What is Data Mining Algorithm? A data mining algorithm can be understood as a set of heuristics and calculations that are used for creating a model from a data. There are...

8 minutes read.

Data Mining Tools

Data Mining Tools and Techniques Data is priceless and it is not very easy to analyze. Data mining is the process in which the user searches and finds out different patterns among...

4 minutes read.

Data Pre-processing in Data Mining

What is the meaning of Data Pre- processing? Data Pre- processing is a very important or crucial phase in Data Mining. However, it is often neglected which should never be done. The...

4 minutes read.

Regression in Data Mining

Regression in Data Mining Regression can be defined as a data mining technique that is generally used for the purpose of predicting a range of continuous values (which can also be...

3 minutes read.

Data Mining Techniques

Data Mining Techniques Let us discuss each one of these techniques in detail: Classification: The technique used for obtaining important and relevant information about data and the metadata is called classification. As we...

4 minutes read.

Clustering in Data Mining

What is meant by Clustering in Data Mining? Clustering in Data Mining can be defined as classifying or categorizing a group or set of different data objects as similar type of...

4 minutes read.

Outlier Analysis in Data Mining

What are Outliers? Outliers are an integral part of data analysis. An outlier can be defined as observation point that lies in a distance from other observations. An outlier is important as...

3 minutes read.

Data Mining Tutorial

Data Mining Introduction Generally, Mining means to extract some valuable materials from the earth, for example, coal mining, diamond mining, etc. in terms of computer science, “Data Mining” is a process...

11 minutes read.