
Intelligent Agents | Agents in AI
What is an Agent?
An agent can be viewed as anything that perceives its environment through sensors and acts upon that environment through actuators.
For example, human being perceives their surroundings through their sensory organs, known as sensors and take actions using their hands, legs, etc., known as actuators.
Diagrammatic Representation of an Agent
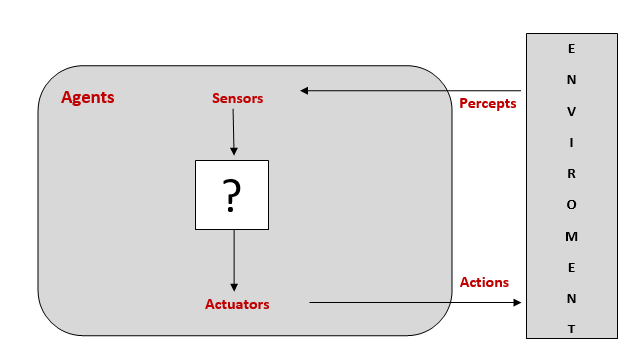
Agents interact with the environment through sensors and actuators
Intelligent Agents
An intelligent agent is a goal-directed agent. It perceives its environment through its sensors using observations and built-in knowledge and acts upon the environment through its actuators.
Rational Agents
A rational agent takes the right action for every perception, hence maximising its performance measure. This makes any agent appear successful based on the current situation.
Example: Chess AI
Omniscient Agents
An omniscient agent is an agent which knows the actual outcome of its action in advance. However, such agents are impossible in the real world.
Example: Tic-tac-toe AI is the closest example
Software Agents
It is a software program that works in a dynamic environment. These agents are also known as Softbots because all body parts of software agents are software only. For example, video games, flight simulators, etc.
Behaviour of an Agent
Mathematically, agent behaviour can be described in two parts:
Agent Function: It is the mapping of a given percept sequence to an action. It is an abstract mathematical explanation.
Agent Program: It is the practical and physical implementation of the agent function.
For example, an automatic hand dryer detects signals (hands) through its sensors. When we bring hands near the dryer, it turns on the heating circuit and blows air. When the signal detection disappears, it breaks the heating circuit and stops blowing air.
Rationality of an agent
It is expected by an intelligent agent to act in a way that maximises its performance measure. Therefore, the rationality of an agent depends on four things:
- The performance measure which defines the success criterion.
- The agent's built-in knowledge about the environment.
- The actions that the agent can perform.
- The agent’s percept sequence until now.
Example: Our exam score not only depends on what we know but also on what is asked in the exam itself.
Note: Rationality maximises the expected performance, while perfection maximises the actual performance, which leads to omniscience.
Task Environment
A task environment is a problem to which a rational agent is designed as a solution. Consequently, in 2003, Russell and Norvig introduced several ways to classify task environments. However, before classifying the environments, we should be aware of the following terms:
Performance Measure (P)
It specifies the agent’s sequence of steps taken to achieve its target by measuring different factors.
Environment (E)
It specifies the interaction of the agent in different environments.
Actuators (A)
It specifies the way the agent affects the environment by taking expected actions.
Sensors (S)
It specifies the way the agent gets information from its environment.
These terms are acronymically called as PEAS. To understand this in more detail, let’s discuss each element in the following example:
| Agent Type | Performance | Environment | Actuators | Sensors |
| Taxi Driver | Safe, fast, correct destination | Roads, traffic | Steering, horn, breaks | Cameras, GPS, speedometer |
| PEAS summary for an automated taxi driver | ||||
Comparing different Task Environments
Fully Observable vs. Partially Observable
When an agent’s sensors allow access to the complete state of an environment at each point in time, then the task environment is fully observable, whereas if the agent does not have complete or relevant information about the environment, then the task environment is partially observable.
Example: In a game like chess, the agent can completely observe the environment, whereas in a game like poker, the agent can only observe the environment partially, as it cannot see the cards of the other agent.
Single-agent vs. multi-agent
When only one agent works to achieve a goal, it is known as a single agent, whereas when two or more agents work together to achieve a goal, they are known as multi-agents.
Example: Solving a sudoku puzzle (single agent), playing chess (multi-agent – 2 agents)
Deterministic vs. Stochastic
If the agent's current state and action completely determine the next state of the environment, then the environment is deterministic, whereas if the next state cannot be determined from the current state and action, then the environment is stochastic.
Example: Image analysis (Deterministic), driving a car in traffic (Stochastic)
Note: If the environment is partially observable, it may appear as Stochastic.
Episodic vs. Sequential
If the agent's episodes are divided into atomic episodes and the next episode does not depend on the previous state actions, then the environment is episodic, whereas if current actions may affect the future decision, such environment is sequential.
Example: Part-picking robot (Episodic), playing chess (Sequential)
Static vs. Dynamic
If the environment changes with time, such an environment is dynamic; otherwise, the environment is static.
Example: Crossword puzzles have a static environment, while the Physical world has a dynamic environment.
Discrete vs. Continuous
If an agent has a finite number of actions and states, then the environment is discrete; otherwise continuous.
Example: A game of chess is discrete since it has a finite number of moves, whereas driving a truck is continuous as one cannot tell for how long it would go on.
Known vs. Unknown
In a known environment, agents know the outcomes of their actions, but in an unknown environment, agents need to learn from the environment to make good decisions.
Example: A tennis player knows the rules and outcomes of their actions, while a new player needs to learn the rules and conditions.
Note: A known environment is partially observable, but an unknown environment is fully observable.
Structure of Agents | Agent Structure in AI
The goal of artificial intelligence is to design an agent program that implements an agent function, i.e., mapping from senses into actions. A program requires some computer devices with physical sensors and actuators for execution, which is known as the agent architecture.
Therefore, an agent is the combination of the architecture and the program, i.e.
AGENT = ARCHITECTURE + PROGRAM
Note: The difference between the agent program and agent function is that an agent program takes the current percept as input, whereas an agent function takes the entire percept history.
Types of Agent Programs
Varying in the level of intelligence and complexity of the task, the following four types of agents are there:
1) Simple reflex agents
It is the simplest agent that acts according to the current percept only and pays no attention to the rest of the percept history. The agent function of this type relies on the condition-action rule – "If condition, then action." It makes correct decisions only if the environment is fully observable. These agents cannot ignore infinite loops when the environment is partially observable but can escape from infinite loops if the agents randomise their actions.
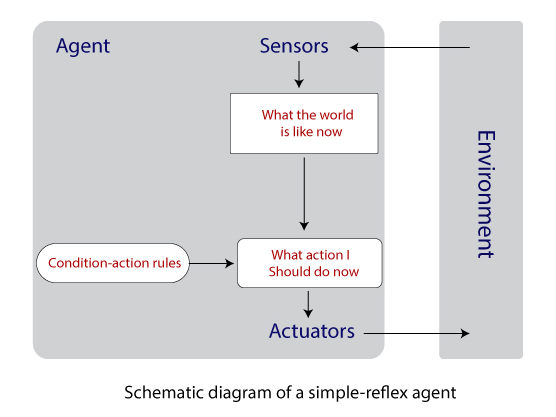
Example: iDraw, a drawing robot that converts the typed characters into writing without storing the past data.
Note: Simple reflex agents do not maintain the internal state and do not depend on the percept theory.
2) Model-based agent
These types of agents can handle partially observable environments by maintaining some internal states. The internal state depends on the percept history, which reflects at least some of the unobserved aspects of the current state. Therefore, as time passes, the internal state needs to be updated, which requires two types of knowledge or information to be encoded in an agent program, i.e., the evolution of the world on its own and the effects of the agent's actions.
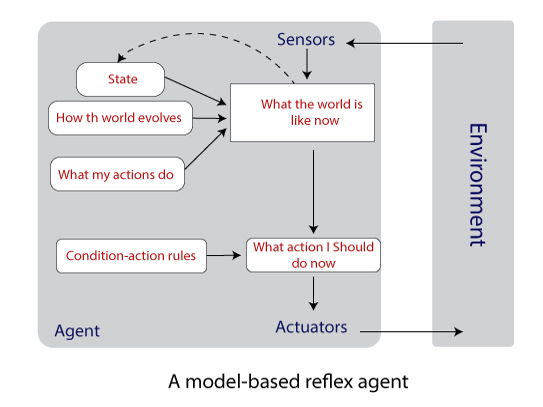
Example: When a person walks in a lane, he maps the pathway in his mind.
3) Goal-based agents
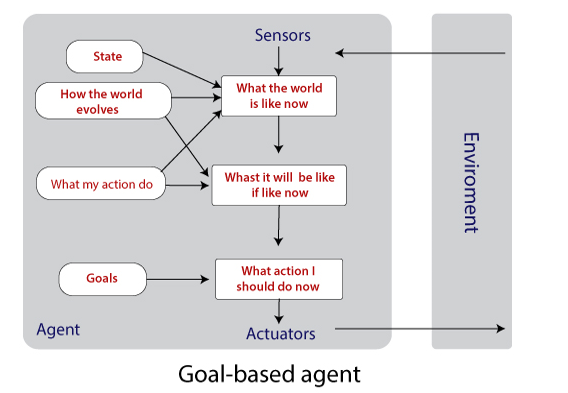
It is not sufficient to have the current state information unless the goal is not decided. Therefore, a goal-based agent selects a way among multiple possibilities that helps it to reach its goal.
Note: With the help of searching and planning (subfields of AI), it becomes easy for the Goal-based agent to reach its destination.
4) Utility-based agents
These types of agents are concerned about the performance measure. The agent selects those actions which maximise the performance measure and devote towards the goal.
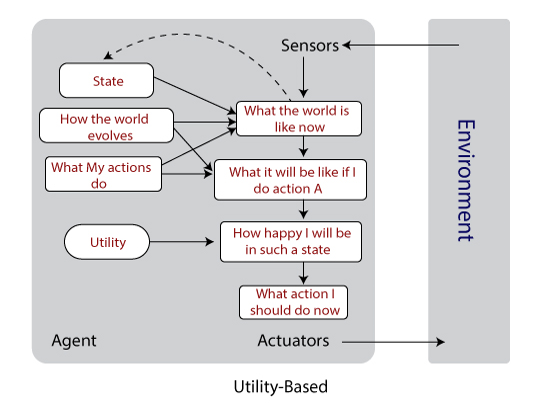
Example: The main goal of chess playing is to 'check-and-mate' the king, but the player completes several small goals previously.
Note: Utility-based agents keep track of their environment, and before reaching their main goal, they complete several tiny goals that may come in between the path.
5) Learning agents
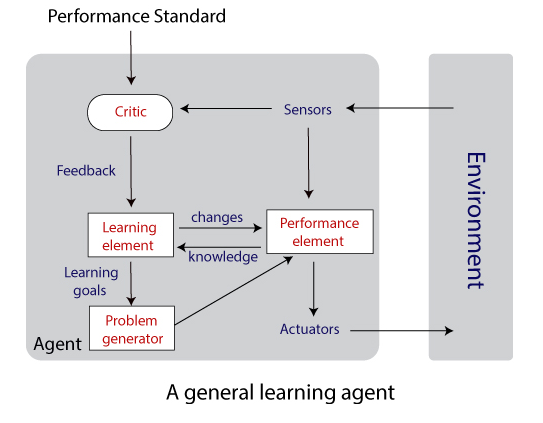
The main task of these agents is to teach the agent machines to operate in an unknown environment and gain as much knowledge as they can. A learning agent is divided into four conceptual components:
- Learning element: This element is responsible for making improvements.
- Performance element: It is responsible for selecting external actions in accordance with the inputs taken.
- Critic: It provides feedback to the learning agent about how well the agent is doing, which could maximise the performance measure in the future.
- Problem Generator: It suggests actions that could lead to new and informative experiences.
Example: Humans learn to speak only after they are born.
Note: The objective of a Learning agent is to improve the overall performance of the agent.
Working on an agent program's components
The function of agent components is to answer some basic questions like “What is the world like now?”, "what do my actions do?” and many more.
We can represent the environment inherited by the agent in various ways by distinguishing on an axis of increasing expressive power and complexity as discussed below:
Atomic Representation
Here, we cannot divide each state of the world. So, it does not have any internal structure. Search, game-playing, Hidden Markov Models, and Markov decision process all work with the atomic representation.
Factored Representation
Here, each state is split into a fixed set of attributes or variables having a value. It allows us to represent uncertainty. Constraint satisfaction, propositional logic, Bayesian networks, and machine learning algorithms work with the Factored representation.
Note: Two different factored states can share some variables like current GPS location, but two different atomic states cannot do so.
Structured Representation
Here, we can explicitly describe various and varying relationships between different objects that exist in the world. Relational databases and first-order logic, first-order probability models, and natural language understanding underlie structured representation.
Related Posts:
- Top 10 Artificial Intelligence Technologies in 2020.
- Forward Chaining in AI : Artificial Intelligence
- Backward Chaining in AI: Artificial Intelligence
- Propositional Logic
- Knowledge Based Agents in AI
- Knowledge Representation in AI
- Cryptarithmetic Problem in AI
- Constraint Satisfaction Problems in Artificial Intelligence
- Alpha-beta Pruning | Artificial Intelligence
- Heuristic Functions in Artificial Intelligence
- Problem-solving in Artificial Intelligence
- Artificial Intelligence Tutorial | AI Tutorial