
×

What is the difference between DFS and BFS?

What is BFS?

BFS is generally known as the low level traversal. As we already know that it stands for breadth first search and is mainly used in the queue data structure. In this, we generally take up any node as the root node. It is generally a graph traversal algorithm that begins negotiating the graph from the initial node and inspects all the other nodes as well. After this, it chooses a node which is the closest and then traverses all the other unvisited nodes. When we use Breadth first search algorithm, we can easily use any node and consider them as the root node. There appears to be a lot of other methods as well to approach the graph for the traversal but BFS is known to be the most commonly used. It is generally categorized as a recursive algorithm which implies that it repeats itself. This algorithm is used to find all the vertices and nodes of a tree or graph data structure. This algorithm mainly categorizes a graph into two sub categories that are visited and non-visited. It chooses a single node from anywhere in the graph and then explores all the other adjacent nodes beside the chosen node. The BFS algorithm for a graph is nearly similar to that of a tree with the only difference that a graph might contain cycles in them. In this kind of algorithm, all the adjacent nodes are inquired before moving to the next level. It is based on the mechanism of adding adjacent nodes to the traversal line beginning from the initial node.
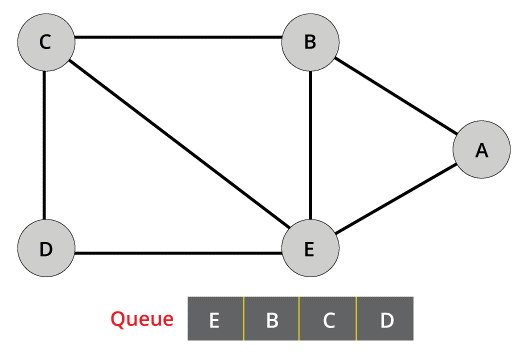
WHAT IS THE DIFFERENCE BETWEEN DFS AND BFS

What is DFS?

DFS stands for Depth First Search. Generally, it is a repetitive or decidable type of algorithm which is basically used in identifying all the vertices or nodes of a graph or tree data structure. It begins its hunt from the initial node in the graph G and hunts deeper and deeper until it reaches its goal which is also known as the goal node or the node that has no children. Due to its repetitive or to be more precise recursive behavior, the stack data structure is used in order to implement the DFS algorithm.

The stack data structure is generally used for this kind of traversal. The stack data structure works on the LIFO principle. LIFO stands for ‘Last In First Out’. In this type of algorithm, we can generally begin from any given node or anywhere unless and until the root node is mentioned in the problem. We can consider any node as the root node.
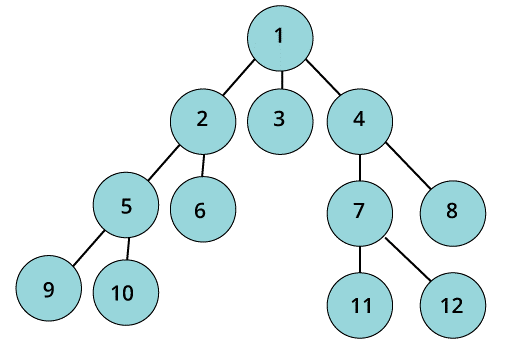
WHAT IS THE DIFFERENCE BETWEEN DFS AND BFS

The major differences between DFS and BFS
WHAT IS THE DIFFERENCE BETWEEN DFS AND BFS
 BFSDFS
Full FormIt stands for Breadth First Search.It stands for Depth First Search.
TechniqueBFS is considered to be a technique that is based on vertex as it has to find the quickest path.DFS is considered to be a technique that is based on edge because as we know that the edges are inspected more than the rest of the nodes present.
DefinitionIt is type of traversal method in which we first inspect all the nodes of a given level and then we move on to the next node or level.It is also a type of traversal technique where it begins with the root node and then begin investigating every other node till the time we find a particular node that is not visited.
Data StructureIn this, queue data structure is usually used for the traversal technique.In this, stack data structure is usually used for the traversal technique.
BachtrackingBacktracking is not possible in this type of traversal.Backtracking is possible in this type of traversal. It generally uses this method to check all the unexplored nodes.
Number of edgesAs we know, BFS is known for searching the quickest path and so it contains a minimum number of edges from the beginning itself.Whereas in DFS, there are a lot of edges needed to commute from the first node to the final node.
OptimalityThis kind of traversal is great for the kind of vertex that is closer to the origin vertex.This kind of traversal is great for the kind of graphs that are at a certain distance to the origin vertex.
SpeedIt is known that BFS is much slower than DFS.It is known that DFS is much quicker and efficient than BFS.
Decision treeBFS traversal is known to be not valid for the decision tree as it requires individual visit to all the adjacent nodes initially.DFS traversal is known to be valid for the decision tree as it visits every path individually which helps in finding the goal.
MemoryThis type of traversal technique is known to be less efficient in terms of memory as it has more memory requirement as compared to DFS.This type of traversal technique is known to be more efficient in terms of memory as it has less memory requirement as compared to BFS.

Related Topics

Queue Implementation using stacks Data Structure

Queue Implementation using stacks In this problem, we have stack data structure which supports only push() and pop() operations. We are required to implement a queue data structure using the instances...

4 minutes read.

What is the difference between DFS and BFS?

What is BFS? BFS is generally known as the low level traversal. As we already know that it stands for breadth first search and is mainly used in the queue data...

4 minutes read.

Check if a Singly Linked List is Palindrome

Check if a Singly Linked List is Palindrome In this section, we have given a singly linked list, and we need to check whether the given list is a palindrome. Example:           1...

3 minutes read.

Blowfish algorithm

The Blowfish algorithm is the very first encryption algorithm which is symmetric. It was firstly used as an alternate algorithm for the DES algorithm. It was designed by Bruce Steiner...

3 minutes read.

LCA of binary tree

Implementation //Writing a program to find the lowest common factor in a given binary search tree. #include <iostream> #include <vector> using namespace std; // the very first step is to create a binary tree. struct __nod { int...

8 minutes read.

What Is Graph Data Structure

A graph is generally a set of vertices and edges or border that is mainly used to join these vertices. A graph is basically pictured as a cyclic tree in...

7 minutes read.

Balanced Binary Tree

A balanced binary tree is just a random nod-based tree with a rule of keeping its height minimum in size to maintain various operations such as insertions, deletions and several...

3 minutes read.

Given a Binary Tree Check the Zig-Zag Traversal

Implementation // The C++ implementation of the zig-zag traversal method in the O(n) time.  #include <iostream> #include <stack> using namespace std; // creating a binary tree node. struct __nod { int record; struct __nod *Lft, *Rt; }; // creating a...

4 minutes read.

Binary Search

Binary Search: When there is a large data structure, the linear search takes a lot of time to search the element. The binary search was developed to overcome the lack...

7 minutes read.

Sorting Algorithms in Data Structures

A sorting algorithm is used to organize the elements of an array or list. Sorting an array, for example. Unsorted array 572941 Sorted array 124579 We're sorting the array in ascending order right now. This procedure...

4 minutes read.

Delete the Middle element of the Linked List in C

Delete the Middle element of the Linked List in C This article has given a singly linked list and will delete the middle element of the given linked list. Example:  The given...

3 minutes read.

Primitive Data Structure in C

The data structure is a logical or mathematical model for organizing and structuring the main memory or elements. We can classify the data structures in two ways one is primitive, and...

10 minutes read.

Union and Intersection of two Linked Lists

Union and Intersection of two Linked Lists This article explains how we can do the union and intersection of two linked lists. In this problem, we have given two linked lists...

3 minutes read.

Why is Binary Heap Preferred over BST for Priority Queue

A priority queue is a linear and ordered collection of elements in which each element has an attribute named priority and the priority attribute decides the order in which elements...

2 minutes read.

Implementation of stack

Implementation of stack: The stack can be implemented in two ways: using array and using a linked list. The pop and push operations in the array are simpler than the...

3 minutes read.

Hash Table vs STL Map

Hash table and STL map are extremely valuable information structures in software engineering. Here we will consider the examination between their properties to be well as execution.  To start with, we will...

7 minutes read.

Bookshop management system using file handling in C++

We see different software in every hospitals or library to manage their database. It is very important to store organization’s data. So we use this software. Now we are going...

5 minutes read.

Object-Oriented Analysis and Design

While designing a system, one should know all the requirements or needs of the plan beforehand, and to do so, we should use a systematic approach to analyze the goal...

3 minutes read.

Lowest Common Ancestor in a Binary Tree

The lowest node in the tree that contains both n1 and n2 as descendants is the lowest common ancestor (LCA), and n1 and n2 are the nodes for which we...

11 minutes read.

Convert Binary Tree into a Threaded Binary Tree

Implementation /*Writing a C++ program that will help us change the binary tree into a threaded binary tree and help us transform. */ #include <bits/stdc++.h> using namespace std; /*Creating the structure of a node...

11 minutes read.