
Sklearn in Python
Scikit-learn or sklearn is a machine learning library used in Python that provides many unsupervised and supervised learning tools and algorithms. David Cournapeau first created it as a 2007 Google Summer of Code project.
In this article, we will discuss sklearn, how to install it in our system, what are the prerequisites of sklearn, what features it provides, and its limitation.
What are Scikit-learn or Sklearn?
Scikit-learn or sklearn is an open-source Python package for machine learning. Sklearn supports reinforcement, supervised, and unsupervised machine learning. It provides many model fitting, selection, data preprocessing, and evaluation tools.
Various regression, classification, and clustering algorithms include random forests, Hierarchical clustering, OPTICS, k-means, boosting, support vector machines, Least Angle Regression, etc. It is also built to work with Python's NumPy and SciPy scientific and numerical libraries.
Prerequisites of Sklearn
Make sure you have installed the necessary libraries before using the most recent Scikit-Learn release:
- Python (version 3.5 or greater)
- NumPy (version 1.11.0 or greater)
- SciPy (version 0.17.0 or greater)li
- Joblib (version 0.11 or greater)
- Matplotlib (version 1.5.1 or greater): this library is used for visualizing the data we processed by plotting various graphs or charts.
- Pandas (version 0.18.0 or greater): this library provides the necessary data structure for analysis.
Installation of sklearn
- Installing using pip
The use of pip may install Sklearn. Write the command given below to install sklearn in your system.
pip install -U scikit-learn
- Installing via connda
It can also be installed by using conda. Write the command given below to install sklearn in your system.
conda install scikit-learn
Note: Make sure NumPy and SciPy are installed before installing scikit-learn.
Why We use Sklearn
Sklearn is a well-documented and easy-to-learn library. It is flexible and integrates well with other Python libraries, such as numpy for array vectorization, pandas for dataframes, and matplotlib for visualization. With the help of this high-level library, you can quickly construct a predictive data model and use it to suit your data.
It provides the following benefits: it is viral and used among data scientists.
Benefits of Sklearn
- Detailed Documentation: It provides API documentation that users can access at any time on the internet, making it easier for them to incorporate machine learning into their platforms.
- BSD license: Because sklearn is distributed under a BSD license, there are few restrictions on its usage and distribution, making it accessible to all users and free of charge.
- Algorithms: Sklearn includes a lot of algorithms for machine learning.
- Easy to use: Sklearn is very easy to use; hence its popularity is huge.
- Algorithm flowchart: Sklearn has a cheat sheet that contains the algorithms, their implementations, and their flowcharts. When a programmer is stuck or confused, he may take reference from here to which algorithm he can use.
- Strong community support: Python is simple to use and understand and already has a large user base, allowing for machine learning performance in a platform familiar to its users.
- Ability to solve various problems: Sklearn can solve all problems in Machine Learning. Such as supervised learning, reinforcement learning, and unsupervised learning.
Features of Sklearn
- Decision Tree: A Decision Tree is one of the tools sklearn provides. It solves the problems of regression and classification and has roots and nodes that build a tree-like model. Nodes indicate an output variable value, whereas roots reflect the choice to divide.
- Datasets: Sklearn has some built-in datasets. These datasets are suitable for beginners. Examples of datasets are the Optical recognition of handwritten digits dataset, Iris plants dataset, Boston house prices dataset, etc. The main benefits of these datasets are that they are straightforward to understand and that ML models can be applied to them immediately.
- Cross-validation: Scikit-learn can be used to test the accuracy and validity of supervised models using unobserved data.
- Supervised learning algorithms: Sklearn has almost all supervised learning algorithms such as Generalized Linear Regression, Least Angle Regression, Stochastic Gradient Descent - SGD, Quantile Regression, Support Vector Machines, etc. Nearly all prominent supervised learning algorithms are included in Sklearn.
- Unsupervised learning algorithm: K-means, OPTICS, Affinity Propagation, Mean Shift, DBSCAN, Spectral clustering, Hierarchical clustering, BIRCH, etc. unsupervised learning algorithm sklearn contains.
Contributors of the Sklearn Community in Python
Everyone is welcome to participate in the Scikit-learn community project. So on https://github.com/scikit-learn/scikit-learn, this project is hosted.
Currently, the following individuals are responsible for the creation and upkeep of Sklearn:
Joris Van den Bossche (Data Scientist), Thomas J Fan (Software Developer), Alexandre Gramfort (Machine Learning Researcher), Olivier Grisel (Machine Learning Expert), Nicolas Hug (Associate Research Scientist), Andreas Mueller (Machine Learning Scientist), Hanmin Qin (Software Engineer), Adrin Jalali (Open Source Developer), Nelle Varoquaux (Data Science Researcher), Roman Yurchak (Data Scientist)
Modelling Process in Scikit Learn
In this chapter, the modelling procedure in use by Sklearn is covered.
Let's have a detailed discussion of this before starting with dataset loading.
Dataset Loading
3Dataset refers to a group of data. It has the two elements listed below:
- Features
Data characteristics are its variables and are referred to as characteristics, predictors, or inputs. Two parts of the Features are the following:- Feature Matrix: If there are several features, Feature Matrix is the collection of those features.
- Feature Name: The list of all feature names is referred to as the feature name list.
- Response
The feature variables only affect the output variable and are sometimes referred to as output, target, or labels. Two parts of the Response are the following:- Response Vector: It stands in for the response column. Typically, there is only one response column.
- Target Names: It indicates the potential values that a response vector might take.
A few example datasets are available in Scikit-learn, including the Boston housing prices for regression and the iris and digits for categorization. Let’s understand it with the help of one example.
Example
From sklearn.datasets import load_iris
import pandas as pd


iris = load_iris()
X_data = iris.data
features = iris.feature_names


Y_data = iris.target
target_names = iris.target_names
X_df = pd.DataFrame(data=X_data, columns=features)


print(f'''x-axis data
{X_df.head(7)}


response values
{target_names}
''')
Output
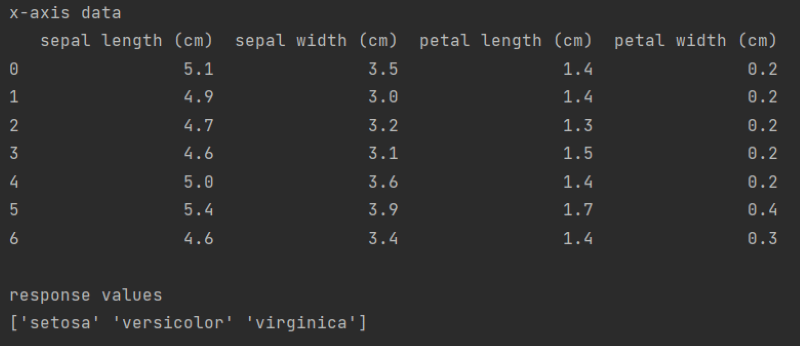
In the above example, we have taken the iris dataset. First, we imported load_iris from sklearn.dataset, we have created the object of this data set using the load_iris() method. We get a 2D array by using the iris.data and iris. The feature gave us the name of columns. Using pandas, we created a table of this data and printed it.
Advantages of Scikit-learn in Python
The advantages of scikit-learn are given below:
- Scikit-learn utilization is simple.
- The development of neuroimages, for example, or the prediction of consumer behaviour, are a few examples of the practical uses of the scikit-learn package.
- The library's BSD license is distributed under makes it freely available with the fewest possible legal and licensing limitations.
- Numerous authors, contributors, and a sizable international online community support and improve Scikit-learn.
- For customers that want to integrate the algorithms with their platforms, the scikit-learn website offers comprehensive API documentation.
Disadvantages of Scikit-learn in Python
The advantages of scikit-learn are given below:
- Inability to Reasonably does Automatic Machine Learning (AutoML).
- Inability to Reasonably do Deep Learning Pipelines.
- scikit-learn is not ready for production nor for Complex Pipelines.
- The best option for in-depth learning is not this one.
Limitations of Scikit-learn in Python
There are some limitations of scikit-learn in Python.
An excellent tool for data exploration, transformation, and classification is Scikit-learn. However, it is tailored for learning techniques like Linear Discriminant Analysis, Logistic Regression, and Support Vector Machines (SVMs) (LDA). Both string processing and graph methods are not well suited for it.
For instance, scikit-learn does not include a built-in method to create a straightforward word cloud. Because Scikit-learn lacks a robust linear algebra package, scipy and numpy are employed. While it lacks a built-in charting library, it allows the use of other plotting libraries.
Conclusion
Regrettably, most machine learning frameworks and pipelines, like scikit-learn, fail to integrate deep learning algorithms into tidy pipeline abstractions that enable clean code, automatic machine learning, parallelism & cluster computing, and production deployment. While Scikit-learn already has these attractive pipeline abstractions, they are still missing essential components for performing AutoML, deep learning pipelines, and more complicated pipelines, such as those for product delivery.
Indeed, we found some design patterns and solutions that combine. The best is simplifying the coding process for software developers and incorporating concepts from the newest frontend frameworks (such as component lifecycle) into machine learning pipelines with the appropriate abstractions to open up more possibilities. With a clever approach, we also overcome the parallelism restrictions of scikit-learn and Python, making it simpler to parallelize and serialize pipelines for use in production. We also make it possible to use complicated modifying pipelines for unsupervised pre-training and fine-tuning.
Sklearn in Python fills this demand for novices and those handling supervised learning problems due to the expansion and popularity of machine learning languages. Scikit-learn is a top choice of academic and industrial organizations for carrying out various tasks because of its effectiveness and adaptability.