
×

StandardScaler in Sklearn

When and How Should You Use StandardScaler?

StandardScaler comes into play whenever the properties of the provided dataset change significantly within their ranges or are recorded in different measurement units.

Since using StandardScaler to lower the average to 0, the data are scaled to have a variance of 1. Unfortunately, extreme values within the data have a significant impact on determining the empirical mean and standard deviation of the data, which reduces the range of characteristic values.

Those changes within initial characteristics could cause problems for so many methods of machine learning. If a dataset's feature has values with wide or drastically diverse ranges, that specific feature of the dataset will govern the distance computation using algorithms that compute distance.

The sklearn StandardScaler function is based on the concept of variables within a dataset with values spanning a number of ranges that may not contribute evenly to the model's fit parameters and training function and may even generate bias in the model's predictions.

Therefore, before including the features in the machine learning model, we must normalise the data (= 0, = 1). To overcome this possible problem, feature engineering standardization is frequently used.

Using Sklearn to standardise

sklearn.preprocessing.StandardScaler(*, copy = True, with_mean = True, with_std = True) 

By eliminating the mean from the features and scaling them to a unit variance, properties were normalised using this technique.

The formula for determining a feature's standard score is z = (x - u) / s, where u is the mean of the training feature (or zero if mean = False) but also s is the sample standard deviation (or one if std = False).

Using the relevant data on the characteristics in the training dataset, primary character and scaling are applied separately to each feature. The fit() function then retains the mean and standard deviation for use with further samples using transform().

Parameters

1. copy: Make an effort to prevent duplicates whether this option is set to True and scale the samples directly. If the input is not a NumPy array or scipy.sparse CSR matrix, for example, that is not always guaranteed to work in place. The function may still produce a duplicate given a sparse CSR matrix.

2. with_mean: Scale the data after centering it if the option is set to True. This doesn't work when applied to sparse matrices (and raises an exception), as centering them requires the creation of a compact matrix, which is often considered too large to fit in the ram under normal use conditions.

3. with_std: When enabled, this option transforms the incoming data to conform to the unit variance (or we can say it makes unit standard deviation). If this is the case, scale the data to unit variance (or equivalently, unit standard deviation).

Attributes

1. scale_: The data is proportionally scaled for each feature, with a zero mean and unit variance.

2. mean_: represents the median value for each feature inside the training sample. This value equals None if the mean parameter is set to False.

3. var_: It represents the variance of each feature in the training dataset. It is employed to establish the features' scale. This value equals None when the std argument is set to False.

4. n_features_in_: The number of features discovered during fitting is provided by this characteristic. The number of characteristics visible during fit.

5. feature_names_in_: The characteristics recognized by names during fitting make up this property. Only when X's feature names are string datatypes is X considered to be defined.

6. n_samples_seen_: This indicates how many samples every feature's estimate looked at.

StandardScaler Example

You need to first import the necessary libraries, import the Sklearn package to utilize the StandardScaler function.

The iris dataset will then be loaded. The sklearn.datasets package contains the IRIS dataset, which we may import.

We'll construct a StandardScaler class object.

Both independent and target traits are separated.

Applying the transformation to the dataset would involve using the fit transform() method.

Syntax:

object_ = StandardScaler()  
object_.fit_transform(features)

Following the above approach, we first created an instance of the StandardScaler() function. We standardize the data by combining the supplied object with fit transform().

Program:

# Data standardization with Python 
# The necessary library is being imported  
from sklearn.preprocessing import StandardScaler  
from sklearn.datasets import load_iris  
# The dataset is loaded 
X, Y = load_iris(return_X_y = True)    
# 3 rows of the original data are printed  
print(X[:7, :6])    
# The process of making a StandardScaler class object  
std_scaler = StandardScaler()   
# 3 rows of the modified data are printed. 
print(std_scaler.fit_transform(X)[:8, :2])  
print(std_scaler.mean_)  

Output:
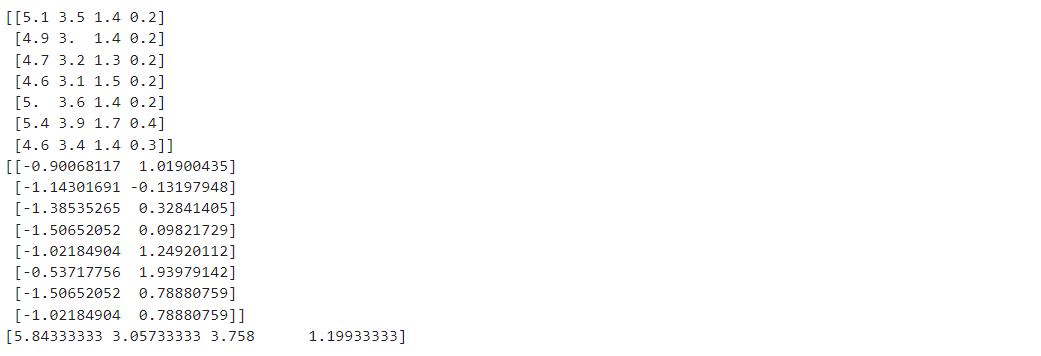
StandardScaler in Sklearn

Related Topics

Character Set in Python

A collection of legal characters that will recognize by a programming language known as a Character set. Taking python programming language as an instance. The set of characters supported by the...

6 minutes read.

Python String Variable

Python programming language: Python is an interactive and more accessible language than any other programming language. The python programming language uses a variety of libraries to perform the operations in a...

4 minutes read.

How to Convert A List into String In Python?

How to Convert A List into String In Python? List is a data structure in Python that can hold values of different data types. The values are enclosed in square brackets...

3 minutes read.

Python Key Error

What is an Error? Errors are nothing but problems in the program which occur in a program code, and this will stop the execution of the program. It is also called...

6 minutes read.

Python Keywords

If you are trying to learn a programming language, you need to have a basic idea of "What are keywords" and "How they are used". You can learn about keywords in...

7 minutes read.

Python - Binomial Distribution

Introduction Definition of the Binomial Distribution The method of counting how many instances of a specific event there have been is called the binomial distribution. It will outline the possible outcomes or...

4 minutes read.

Python coding platform

Python is a popular general-purpose programming language with many applications. High-level data structures, datatypes, dynamic binding, and many other features make it useful for both designing complex applications and "glue...

6 minutes read.

Confusion Matrix Visualization Python

The confusion matrix is a two-dimensional array that compares the anticipated and actual category labels. These are the True Positive, True Negative, False Positive, and False Negative classification categories for...

4 minutes read.

Python Decorator

Python Decorator: A Decorator is an interesting feature of Python that helps the user design patterns and insert a new functionality to an existing object without making any modifications in...

6 minutes read.

Python String startswith() method

Python String startswith() method The string.startswith() method in Python returns a boolean value ‘True’ if the given string starts with the prefix, otherwise it returns False. Syntax startswith(prefix[, start[, end]]) Parameter prefix: This parameter signifies the value to check. start(optional):...

1 minute read.

Python Matrix Operations

Python Matrix In this section of the Python tutorial, we will look at the introduction of the matrix in Python programming. We will perform many operations on the Python matrix using...

21 minutes read.

Falcon Python

Introduction of Python Python is the fastest and the smartest programming language and it is an object oriented language. Python has libraries that can be importedeasily and perform many operations; to...

3 minutes read.

Palindrome In Python

What is Palindrome? A Palindrome can be defined as the number or a string that resides unchanged when it is reversed. Example: 14341 Output: Yes, this is a Palindrome number Example: RACECAR Output: Yes, this...

2 minutes read.

Creating new Database using Python MySQL

In this article, we are going to discuss how to create a new database by connecting Python and MySQL. What is a Database? The places or memory used to secure highly and...

6 minutes read.

Iterate a Dictionary in Python – Part 2

In this tutorial, we will learn above various methods used to Iterate a Dictionary in Python. Dictionary: In Python, a dictionary is an unordered collection of data values that is used to...

3 minutes read.

Data Drop in Python

Introduction You'll understand how to delete a group of rows from a Pandas dataframe in this article.You can read this article on How to Drop Columns in Pandas to find out...

6 minutes read.

Python filter() function

Python filter() function The filter() function constructs an iterator from those elements of iterable for which the parameter ‘function’ returns a Boolean value true. Syntax filter(function, iterable) Parameter function: This parameter represents a function to be run for each item in the...

1 minute read.

Spark and Python for big data with pyspark github

Pyspark: Apache Spark is a computational engine that handles large data sets using parallel and batch processing. Apache Spark is an open-source, distributed computing framework and collection of libraries for real-time,...

3 minutes read.

Difference between Package and Module in Python

What are Python modules? A file with the “.py” suffix that includes Python or C executable code is known as a module. Multiple Python commands and expressions make compose a module....

3 minutes read.

Python datetime

Python provides a module named datetime to work with the date and time. Sometimes in the real life application development, we need to work with the date and time. The date is...

3 minutes read.